# Nick Karnik — Full Corpus
> Nearly three decades building software across search, AI, and developer tools. Engineering leader, writer, cook, dad of three.
All content © Nick Karnik, all rights reserved. Reuse with attribution; cite the canonical URL given under each post.
---
# How Autosuggest Ranking Works
Canonical: https://nick.karnik.io/blog/ranking-autosuggest-results
Published: 2026-07-19
Cite as: Nick Karnik, "How Autosuggest Ranking Works", nick.karnik.io (2026). https://nick.karnik.io/blog/ranking-autosuggest-results
The first time I implemented autosuggest, it was a simple ordered list of suggestions based on prefix matching. Technically correct. You typed a few letters, everything that matched came back.
But people weren't finding what they were looking for. The right answers were there, just buried. Not at position eight or nine, sometimes much deeper. The matching was fine. Everything else was the problem.
I had to think about what better actually meant. Showing everything that matched wasn't enough. There were other factors in play, and the default order wasn't accounting for any of them.
This is how I worked through it. To keep it concrete, picture a recipe search. Someone starts typing the name of a dish and you suggest recipes as they go.
## Matching comes first, and it is not ranking
Someone types "chick" and the first thing that happens is a filter. Every recipe whose name starts with those letters is a candidate. Everything else is not.
"chick" → "chicken soup"    ✓ candidate
"chick" → "chickpea stew"   ✓ candidate
"chick" → "banana bread"    ✗ not a candidate
That is a string comparison, and it is the job of your search index. You do not walk a million recipes checking each one. The index is built so that a prefix jumps you straight to the few hundred that start with those letters.
This matters for everything that follows. Banana bread is not ranked last on a search for "chick." It is not ranked at all. It never enters the conversation. So nothing in the rest of this article needs to defend against a non-match winning, because a non-match is never scored in the first place.
The filter hands you a few hundred candidates. Now you have the actual problem.
## Everything that survives ties
You have room for ten. The filter gave you hundreds, and as far as it is concerned they are all identical, because they all passed the same test.
There is nothing to sort by. So you fall back to the only property you have, which is the name itself, and sort A to Z.
| # | Recipe |
| --- | --- |
| 1 | chicken aspic |
| 2 | chicken curry |
| 3 | chicken parmesan |
| 4 | chicken pot pie |
| 5 | chicken soup |
| 6 | chickpea stew |
Alphabetical order is not wrong. It is just completely unrelated to what anybody wants for dinner. You are sorting by a property of the string instead of a property of the recipe.
What you need is a number that says how relevant each candidate is, so you can sort by that instead. Call it the relevance score. Everything from here is working out what goes into it.
## Add count
The strongest thing you know about a recipe is how many people wanted it. Some get saved constantly. Others sit untouched. That is a number, and unlike the match test, it varies.
It assumes you have it. Every recipe carries a count, and something increments it when a person picks that recipe. Whatever you are ranking, there is usually some version of this already sitting in the data: clicks on a result, plays on a track, views on a page.
**relevance = count**
| # | Recipe | Count |
| --- | --- | --- |
| 1 | chicken curry | 84,000 |
| 2 | chicken soup | 52,000 |
| 3 | chicken parmesan | 31,000 |
| 4 | chicken pot pie | 18,000 |
| 5 | chickpea stew | 9,500 |
| 6 | chicken aspic | 12 |
Look at what was sitting at the top of the alphabetical list. Chicken aspic. Twelve people in the history of the internet have made chicken aspic, and it was the first thing the person saw, because the letter a comes before c. It is now last, where it belongs.
One thing worth knowing before you trust the count too much. It is not a measure of quality, it is a measure of what got seen and clicked. Recipes that rank well get picked more, which raises their count, which makes them rank better. Your strongest signal is partly a record of what your own ranking has already been showing people.
## Log the count
Sorting by count works. The problem is what it does to every signal you add after it.
Chicken curry has a count of 84,000. Chickpea stew has 9,500. That is not a small difference, it is **nine times**. And it is the kind of difference you see constantly in real data, where a few things are wildly popular and everything else is not.
Now suppose you want to add a second signal. Something that knows this person eats vegetarian, so chickpea stew should climb. That signal has to be strong enough to overcome a nine to one popularity difference, or the top of the list never changes.
You cannot make it that strong. If a single preference outweighs nine times the popularity, then popularity has stopped mattering at all, and you have traded one broken ranking for another.
So with raw counts you are stuck. Popularity is so dominant that every other signal you build is decoration. It can nudge things a little, but it can never actually change the answer.
Taking the log fixes this, and it is worth being precise about what it fixes, because it is not what people usually assume.
**relevance = log(count)**
| Recipe | log(count) | Result |
| --- | --- | --- |
| chicken curry | log(84,000) | 4.924 |
| chicken soup | log(52,000) | 4.716 |
| chicken parmesan | log(31,000) | 4.491 |
| chicken pot pie | log(18,000) | 4.255 |
| chickpea stew | log(9,500) | 3.978 |
| chicken aspic | log(12) | 1.079 |
Chicken curry had nine times the count of chickpea stew. After the log it has about 1.2 times the score. The counts still run in the same direction, they are just no longer nine times apart.
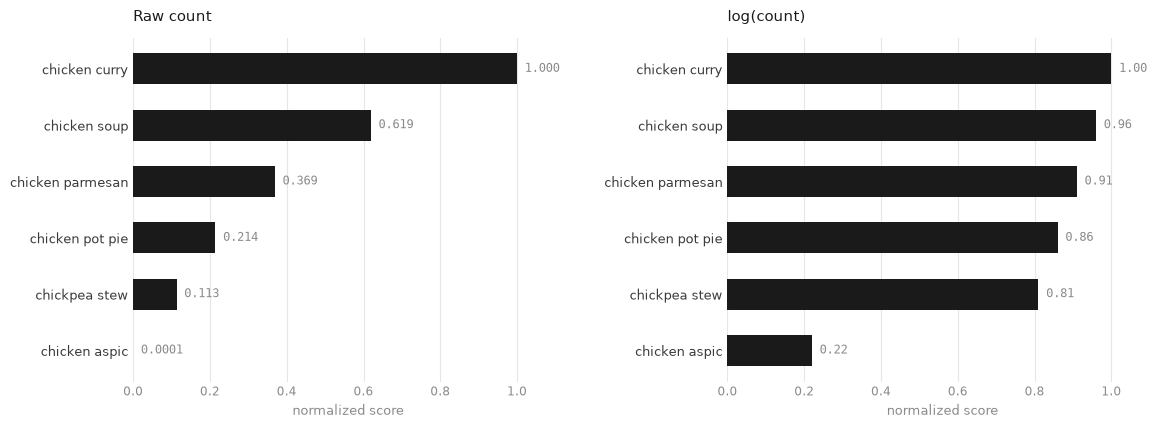
Notice what did not change. The order. Curry is still first, aspic is still last. A bigger count always produces a bigger log, so taking a log cannot reorder anything by itself. If you thought the log was going to fix the ranking, it does not, and it never could.
What it changed is how far apart everything is. A vegetarian preference cannot overcome **nine times** the popularity. It can absolutely overcome **1.2 times**.
**The log does not rank anything. It makes it possible for everything else to.**
Two pieces of housekeeping before moving on. A recipe nobody has picked has a count of zero, and there is no log of zero, so treat it as a count of one. log(1) is 0, meaning a brand new recipe contributes nothing from popularity, and it can still earn points from every other term, which is exactly what a brand new recipe should do. And everything you are about to add will be a small number between 0 and 1, so the count needs to be on that scale too. Divide each log by the largest log in the set, which is 4.924.
| Recipe | log(count) / 4.924 | Score |
| --- | --- | --- |
| chicken curry | 4.924 / 4.924 | 1.00 |
| chicken soup | 4.716 / 4.924 | 0.96 |
| chicken parmesan | 4.491 / 4.924 | 0.91 |
| chicken pot pie | 4.255 / 4.924 | 0.86 |
| chickpea stew | 3.978 / 4.924 | 0.81 |
| chicken aspic | 1.079 / 4.924 | 0.22 |
That is the number that goes in the formula.
## Not every match is equally good
The filter is binary, so it cannot tell a good match from a lazy one. Type "chicken" and all three of these are equally valid candidates:
chicken soup
chicken parmesan
chicken curry with roasted butternut squash
They are obviously not equally good. The person typed seven characters. For the first name that accounts for most of it. For the last it accounts for almost none of it. A short name that the query nearly fills is a confident match. A long name where the query is a small prefix is a guess about where the person was heading.
You can measure that directly. Divide the length of what they typed by the length of the name, and you get how much of the name the query actually covers.
**coverage = length of query / length of name**
| Recipe | Query / name length | Coverage |
| --- | --- | --- |
| chicken soup | 7 / 12 | 0.58 |
| chicken parmesan | 7 / 16 | 0.44 |
| chicken curry with roasted butternut squash | 7 / 43 | 0.16 |
Now the obvious question. If coverage measures match quality, why not filter on it instead of the prefix test?
Because it never returns zero. A recipe that matched always has some coverage, so there is no clean line to cut at, and there should not be one. A weak match is still a match. Someone typing "chick" who wants the long curry recipe should still be able to find it, just not at the top.
So the filter stays binary and coverage joins the relevance score as another term.
**relevance = log(count) + coverage**
## Every other signal is the same move
Once the shape is there, adding a new signal is always the same move. Another term in the sum, lifting recipes that have some property you care about. Coverage was free, because it comes from the name. Everything below needs a field you have to build and keep accurate, which is where most of the real work turns out to live.
Recency rewards recipes people are saving right now. The thing to track is one date per recipe: the last time someone saved it. Every save overwrites it with today, so nothing has to decide what counts as popular, it is just the most recent save. This is not the date the recipe was published. An old recipe can pick up a fresh wave of saves, like a soup in a cold snap, and a brand new one might sit unsaved for months. Recency is about recently wanted, not recently created.
From there you want a number that is high right after a recipe is saved and fades as the days pass. Call it the decay factor. First pick a shelf life, how many days a recipe stays fresh before it counts for nothing, say 140. Then shrink the score evenly across it.
**decay = 1 − (days since saved / shelf life)**
Both sides are plain: days since saved is how long ago the last save was, shelf life is how long you have decided a recipe stays fresh. Take a 140 day shelf life. A recipe saved today scores 1. At 70 days it is halfway down at 0.50. At 140 days it hits 0, and anything older stays at 0 rather than going negative. One number to pick, the shelf life, and the rest is subtraction. Decide how fast your domain moves and the shelf life follows. News is spent in a day. Recipes stay fresh for a season.
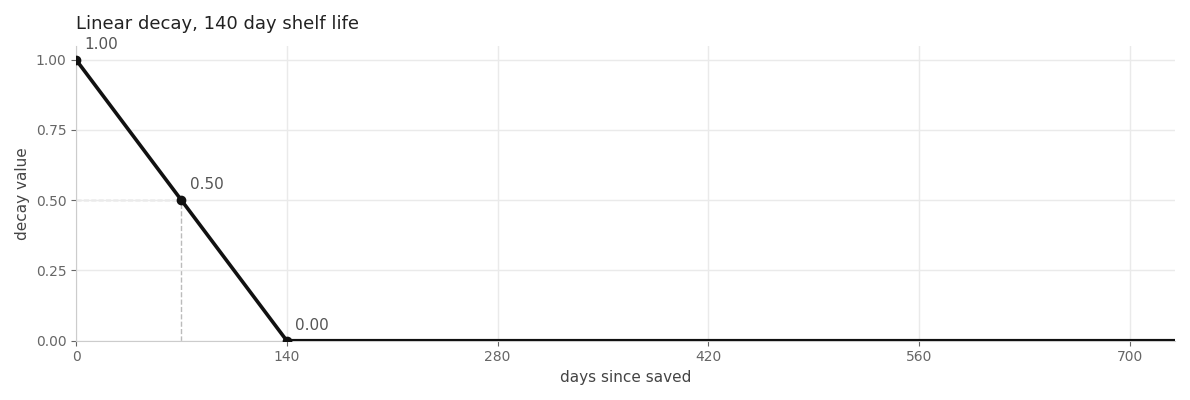
| Last saved | Decay factor |
| --- | --- |
| today | 1.00 |
| 35 days ago | 0.75 |
| 70 days ago | 0.50 |
| 140 days ago | 0.00 |
Bigger systems often swap the straight line for a curve that drops fast at first and then flattens, which fits how attention fades and lets an old favorite keep a sliver of credit. Same idea, a curve instead of a line, and nothing else changes.
Context rewards recipes that fit the situation. It assumes the recipes are tagged, and someone has to decide that chicken soup is a winter dish and shakshuka is breakfast. Editors, the author, or a model reading the ingredients. That is a whole problem of its own.
Once the tags exist, the signal is simple. Each condition you can check is worth a fixed amount, and they stack. Cap the stack at 1, so context stays on the same 0 to 1 scale as every other signal, and its weight in the formula decides what that is worth against popularity.
| Condition | Boost |
| --- | --- |
| Tagged breakfast, and it is morning | +0.5 |
| Tagged winter, and it is December | +0.5 |
| Tagged vegetarian, and they have been browsing vegetarian | +0.5 |
A chickpea stew in December, for someone browsing vegetarian, picks up 1.0 from context. A chicken curry in the same situation picks up nothing. Nothing about the curry got worse, the stew just fits the moment better.
Personalization is the same shape, but the condition is about this specific person rather than the situation. They cook a lot of Thai food, they reach for chickpeas, they have made this recipe before. It assumes a per-user history, which is a bigger commitment than anything above it: accounts, a store that grows with every user, and a privacy posture you can defend.
It also has a cold start. A new person has no history, so the term is zero for them. Nothing breaks, because it is one term among several. They just get the unpersonalized ranking, which is the ranking you spent the rest of the article building.
**relevance = w1·log(count) + w2·coverage + w3·recency + w4·context + w5·personalization**
The w's are weights, one per signal, saying how much each term counts. Every term does the same job. It nudges a recipe up for a reason you can name. That is the whole formula.
## The numbers are precomputed
Looking at that formula, it is easy to picture the server doing a pile of math on every keystroke. It does not. The count, the last-saved date, and the tags are all written onto each recipe ahead of time by a background job. By the time someone starts typing, every number the formula needs is already sitting on the record.
At query time you are reading stored values and doing a little arithmetic on a few hundred candidates, which is why autosuggest can feel instant. Recency is the one exception, because it depends on what today is and has to be computed live, but decay from a stored timestamp is a subtraction, cheap enough that it does not matter.
The expensive work happens before anyone types. The keystroke just reads the answer.
## Weights are tuned, not calculated
There is no formula for the weights. You do not derive them, you guess and correct. But you do not have to guess blindly, because the signals have an obvious pecking order. Popularity is the most reliable thing you know about a recipe, so it gets the largest weight. Everything else adjusts around it.
The weights do not need to add up to 1. Multiply all of them by the same number and not a single position changes, because only their ratios matter. So anchor popularity at 1.0 and read every other weight as a fraction of it. Context at 0.4 means context is worth forty percent of popularity.
| Signal | Weight | Why |
| --- | --- | --- |
| log(count) | 1.0 | Popularity is your most reliable signal. Anchor everything to it. |
| context | 0.4 | Strong enough to reshuffle the top few, not strong enough to bury a favorite. |
| personalization | 0.4 | Same reasoning as context, once you have the history to support it. |
| recency | 0.3 | A recent surge matters, but a classic should not fall off because it peaked last year. |
| coverage | 0.2 | Only there to break ties. If it is deciding anything on its own, it is too high. |
Now watch what those weights do. Same query, "chick". It is December, and this person has been browsing vegetarian recipes all week. Personalization sits this one out: browsing this session is context, and this person has no saved history, so the personalization term is zero for every recipe. That is the cold start from the last section. Every column adds one more signal to the one before it. The first column sets the order. After that, each cell just shows the score, an arrow marks where a rank changed, and first place is always labeled.
| Recipe | count | + coverage | + recency | + context |
| --- | --- | --- | --- | --- |
| chicken curry | **1st** 1.00 | **1st** 1.08 | **1st** 1.37 | ↓ **3rd** 1.37 |
| chicken soup | **2nd** 0.96 | 1.04 | 1.28 | 1.48 |
| chicken parmesan | **3rd** 0.91 | 0.97 | ↓ **4th** 1.14 | ↓ **5th** 1.14 |
| chicken pot pie | **4th** 0.86 | 0.93 | ↓ **5th** 1.04 | ↑ **4th** 1.24 |
| chickpea stew | **5th** 0.81 | 0.88 | ↑ **3rd** 1.17 | ↑ **1st** 1.57 |
| chicken aspic | **6th** 0.22 | 0.30 | 0.30 | 0.30 |
Follow chickpea stew across the row. **Fifth, fifth, third, first.**
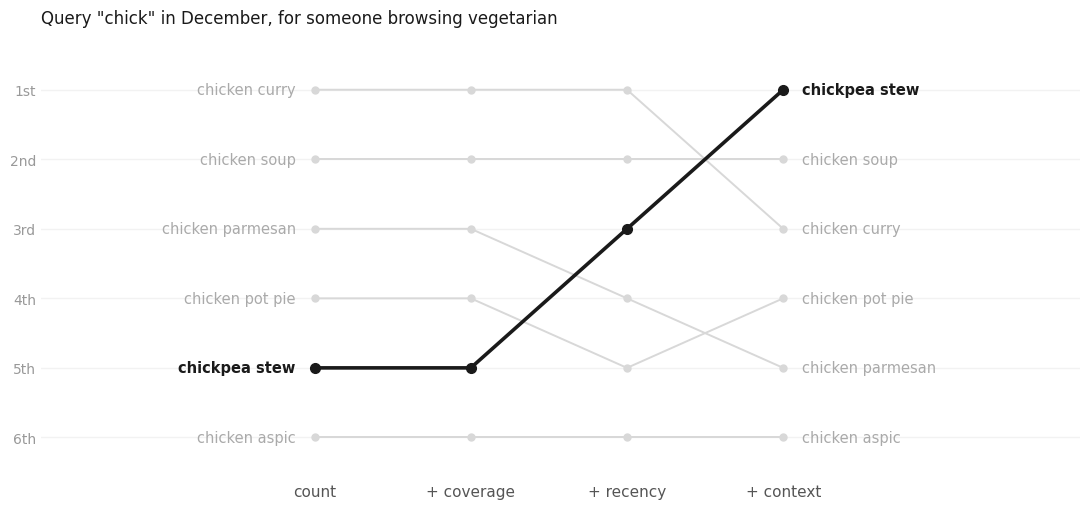
Popularity alone leaves it in fifth. Coverage does not move it at all, which is exactly what a tie-breaker should do. Recency lifts it to third, because it was saved recently. Context puts it on top, because it is December and this person eats vegetarian, and those two conditions together are worth more than the nine times higher count that chicken curry has.
Chicken curry did not get worse. Its score never dropped, not once, in any column. It went from first to third because two other recipes fit this person and this moment better than it did.
One last run, to show the log is what made that climb possible. Same signals, same weights, same person, run twice: once with the popularity term as raw counts divided by the biggest count, once with the log. Here is where everyone finishes in each world.
| Recipe | Raw counts | With the log |
| --- | --- | --- |
| chicken curry | **1st** 1.37 | 3rd 1.37 |
| chicken soup | 2nd 1.14 | 2nd 1.48 |
| chicken parmesan | 4th 0.60 | 5th 1.14 |
| chicken pot pie | 5th 0.59 | 4th 1.24 |
| chickpea stew | 3rd 0.87 | **1st** 1.57 |
| chicken aspic | 6th 0.08 | 6th 0.30 |
Chickpea stew collects every boost it collected before and stalls in third. Curry scores 1.37 in both worlds, but on raw counts nothing can reach it, because the nine to one popularity gap costs stew nine tenths of a point before the other signals even speak. **The middle of the list wiggles. The top does not move.** That is what stuck means, and the log is the only difference between this table and the one above it.
Nudge these numbers, run searches you know the right answers to, and look hard at what comes back wrong. A bad result almost always points at a weight that is too high or too low. Later, once you have data on what people actually cooked, you can learn the weights from behavior instead of intuition.
## When it is done
The formula is never really finished, and new terms come from more than one place. Sometimes a result is visibly wrong and nothing already in the formula explains why. Sometimes it is a product call, like deciding seasonal dishes should surface in season. Sometimes new data shows up, ratings, delivery times, repeat cooks, and you ask whether it earns a term. The test is the same for all of them: add the term, rerun searches you know the right answers to, and keep it only if the results get better.
Nobody designs a ranker like this up front. You start with a filter and no ranking at all, look at what it gets wrong, and let each specific failure pull the next term out of you. Count came from every candidate tying. The log came from the popularity gap being too wide for any other signal to cross. Coverage came from the filter treating a barely relevant name as well as a perfect one. Every piece is there because the version before it broke in a way you could see.
The signals change with the data. A music app would rank by plays and release date. A map would rank by distance and rating. The shape does not change. The filter decides who is a candidate, the relevance score decides the order, and you earn each new term by watching the results tell you it is missing.
---
# Precision vs Recall: Is Your Model Good Enough?
Canonical: https://nick.karnik.io/blog/precision-vs-recall
Published: 2026-05-10
Cite as: Nick Karnik, "Precision vs Recall: Is Your Model Good Enough?", nick.karnik.io (2026). https://nick.karnik.io/blog/precision-vs-recall
In late 2006, I built a sentiment classifier for MSN Shopping. Precision and recall were the gatekeepers. Those numbers decided whether the model shipped or went back for more work.
It took months of effort. Labeling data, tuning features, retraining, evaluating again. With LLMs today, the same thing can be done in minutes.
What has not changed is how you measure whether the model is actually good.
## The problem with accuracy
Accuracy is a single number that tells you how often the model is right. What it hides is what kind of wrong it was when it missed.
Missing a negative review and falsely flagging a positive one both count the same. But for a support team triaging complaints, those mistakes cost very different things.
It also breaks down completely when the data is imbalanced. If only 5% of reviews are negative, a model that calls everything positive is 95% accurate without doing anything useful at all.
## Precision: when the model says yes
Precision measures the quality of positive predictions. Out of everything the model flagged as positive, how much actually was?
**Precision = True positives / (True positives + False positives)**
Low precision means too many false alarms. The model flags aggressively but a lot of those flags are wrong.
A spam filter with low precision is a good example. It catches most spam, but it also routes real emails to your junk folder. The flags are not reliable enough to trust.
## Recall: what the model misses
Recall measures coverage. Out of all the things that were actually positive, how many did the model find?
**Recall = True positives / (True positives + False negatives)**
Low recall means too many missed cases. The model is cautious and only flags what it is very confident about.
A medical screening tool with low recall is dangerous. It might have clean, accurate flags, but it is quietly missing real cases that needed to be caught.
## What this looks like in practice
**Sentiment classifier on 1,000 electronics reviews**
100 reviews are genuinely negative.
The model flags 120 as negative.
Of those 120, only 80 are actually negative. The other 40 are positive or neutral reviews it got wrong.
Of the 100 real negative reviews, the model caught 80 and missed 20.
**Precision:** 80 / 120 = 67%
**Recall:** 80 / 100 = 80%
The model catches most of the real negative reviews but a third of its flags are wrong. Whether that tradeoff is acceptable depends on what you plan to do with the output. If you are surfacing complaints to a support team, false flags waste their time. If you are routing reviews for moderation, missing a real negative review is worse.
## Why you cannot have both
Precision and recall move in opposite directions. Most classifiers output a confidence score and you set a threshold to decide what counts as a positive prediction.
Raise the threshold and the model becomes more selective. Fewer false alarms, but more missed cases. Precision improves, recall drops.
Lower the threshold and the model casts a wider net. More real cases caught, but more false alarms too. Recall improves, precision drops.
The confidence threshold is the number that controls this. Every prediction comes with a score between 0 and 1. If the threshold is set to 0.8, the model only flags something when it is at least 80% confident. Lower it to 0.4 and it flags anything it is 40% sure about, catching more but also making more mistakes.
The right threshold is not a math decision. It comes from understanding which failure is more costly in your situation.
| Situation | The costly mistake | What to do |
| ----------------- | ---------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------- |
| Medical screening | Missing someone who is actually sick. An extra test is a minor inconvenience. Going undiagnosed is not. | Optimize for recall. Lower the confidence threshold so the model flags more cases, even if some turn out to be fine. |
| Spam filter | A real email ending up in junk. Spam getting through is annoying. Missing an important email is worse. | Optimize for precision. Raise the confidence threshold so the model only blocks messages it is very sure are spam. |
| Fraud detection | Fraud that slips through undetected. Flagging a legitimate transaction is minor friction. Missed fraud is a real loss. | Optimize for recall. Lower the confidence threshold so more suspicious transactions get flagged, even if some are legitimate. |
| Search results | Pages nobody wanted. A search full of noise trains people to stop trusting it. | Optimize for precision. Raise the confidence threshold so only the most relevant results make it through. |
## Putting it in one number
When you are talking to a team and trying to align on whether the model is improving, you eventually need one number. That is what F1 is for. It is the harmonic mean of precision and recall, and it rewards balance. A model that does well on both scores high. A model that sacrifices one to game the other does not.
**F1 Score = 2 × (Precision × Recall) / (Precision + Recall)**
Score range: 0–1 | Good: 0.8–0.9 | Perfect: 1.0 (rarely achieved)
On the MSN Shopping classifier, F1 was the number we tracked. The goal was always to push it higher, which meant going back upstream. Better labeled data. More edge cases in the test set. Different features. Sometimes a different algorithm. F1 moved when the underlying work moved. That is what a good metric does. It points at the next thing to fix.
## What precision and recall actually revealed
The model that worked for electronics did not work for autos. Same architecture, same training approach, same accuracy on paper. But the precision and recall numbers told a different story when we looked at each domain separately.
Sentiment in electronics was relatively straightforward. People praise specs, complain about defects, and the language is consistent. Autos was different. A "rough ride" might be a complaint or a feature depending on whether the reviewer wanted a sports car or a sedan. Sarcasm was more common. Context mattered more.
Product reviews were full of terms that threw the model off without deeper context. The word "cancer" might mean the zodiac sign on a piece of jewelry or the disease in a personal story attached to a review. "Killer" might be praise or a complaint. "Sick" might be slang for great or a literal description of a problem. Without understanding the domain, the model picked the wrong sentiment confidently. Accuracy stayed high on average. Precision and recall on the harder cases told a different story.
We could not just retune and ship. Each new domain took roughly six months of work. New labeled data. New evaluation. New thresholds. Sometimes new features entirely. Electronics, autos, then the next category, and the next.
That is the part LLMs have genuinely changed. With prompt engineering or fine-tuning, you can adapt a single model to a new domain in days or weeks instead of months. A few well-crafted instructions, or a small set of domain-specific examples, can move the needle in ways that used to require an entire training cycle.
What has not changed is the need to measure. A clever prompt might look like it solved the problem in a few examples and still fail at scale. Fine-tuning might improve one slice while quietly hurting another. The only way to know is to evaluate precision and recall in the actual domain you care about. The shortcut is in the building. The measuring still has to be done.
Precision asks if the model can be trusted when it says yes. Recall asks if the model is finding everything that matters. Neither is meaningful in the abstract. They only matter inside the context where the model is being used, and that context changes the answer every time.
So how do you tell if a model is good enough? You measure it where it actually has to work. Precision and recall in the right domain. Anything else is a guess.
---
# How Computers Actually Get Compromised Today
Canonical: https://nick.karnik.io/blog/the-modern-attack-surface-how-computers-get-compromised
Published: 2026-01-26
Cite as: Nick Karnik, "How Computers Actually Get Compromised Today", nick.karnik.io (2026). https://nick.karnik.io/blog/the-modern-attack-surface-how-computers-get-compromised
This post started with a simple question a friend asked me: which antivirus should I be using?
It made me pause. Not because the question was wrong, but because it assumed an older model of how things go wrong. Before answering, I found myself asking a more basic question instead.
How are machines even getting compromised these days?
Once you really sit with that question, the antivirus conversation starts to feel secondary.
Operating systems are more locked down than they have ever been. Automatic updates are normal. Sandboxing, permissions, and code signing actually work.
And yet compromises are everywhere.
The reason is simple. The attack surface moved. It is no longer centered on the computer itself. It is centered on identity, sessions, and everyday trust.
## The old mental model most of us still have
For a long time, compromise looked straightforward. Something bad landed on your machine, the computer was infected, and the damage lived there.
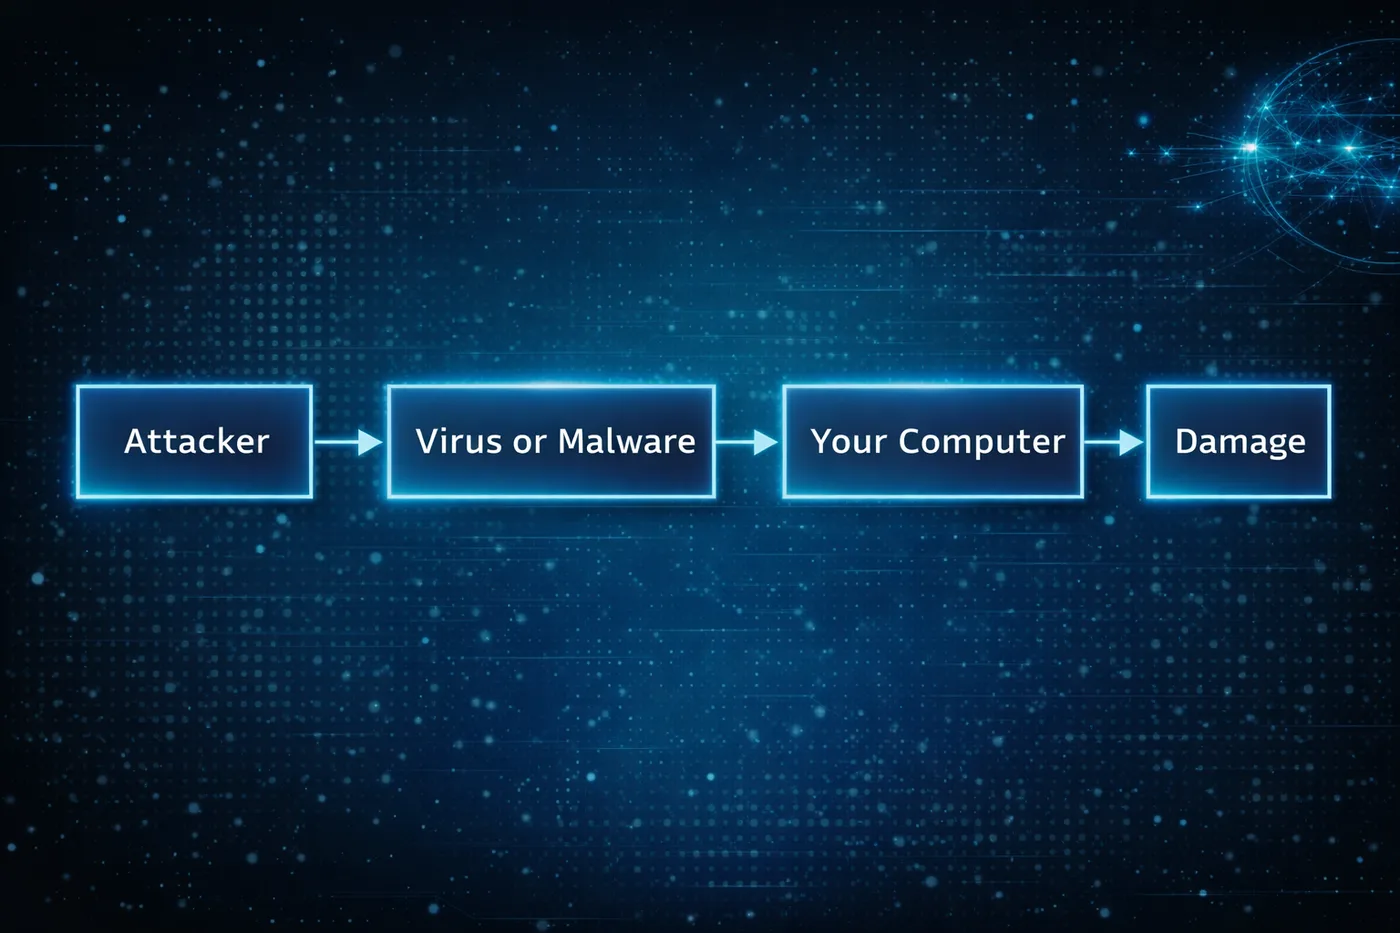
That model made sense when systems were fragile and defenses were thin. If you avoided sketchy downloads, you were mostly safe.
That world quietly disappeared.
## What compromise usually looks like now
Today, the computer is often fine. The operating system is doing its job. Nothing looks obviously broken.
What fails is access.
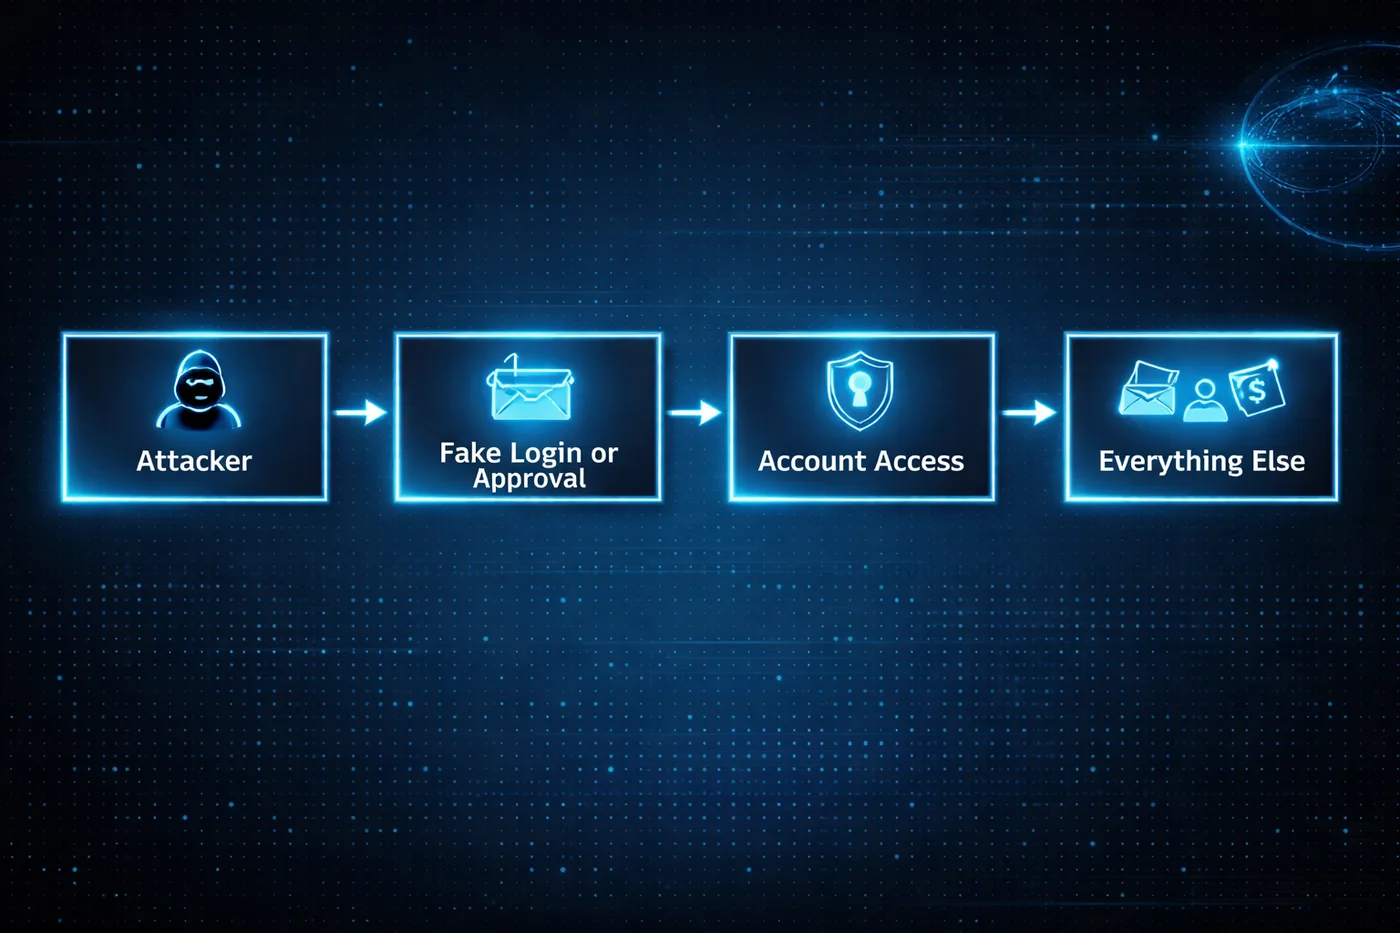
Once someone controls an account, they rarely need to touch the device. Email access alone is enough to reset passwords, read private documents, send convincing messages, and stay invisible for a long time.
This works the same way on Windows, macOS, and iOS. The platform matters far less than people think once trust is lost.
## Why browsers quietly became the real operating system
Most of what matters now happens inside a browser. Email, documents, calendars, dashboards, payments, internal tools. That is where work lives and where trust accumulates.
Modern attacks aim for that session, not the computer underneath it.
A fake login page that looks familiar. A browser extension that seemed useful at the time. A stolen session token that never triggers a password prompt.
Once the browser believes you are authenticated, the rest of the system follows along.
## What this feels like as an end user
For most people, compromise does not feel technical. It feels confusing.
You cannot log into an account you used yesterday. You see password reset emails you did not request. Calendar events appear that you never added. Messages are sent from your account that you did not write. A bank asks you to confirm activity you do not recognize.
Nothing screams virus. It just feels like control slipping.
That uncertainty is often the worst part. You stop trusting your own systems. You hesitate on legitimate prompts because everything suddenly looks suspicious.
I learned this the hard way. In the early 2000s, I used to think the worst that could happen was someone looking at my emails. Then that account got hacked and the attackers deleted everything. I lost all that data, but I was lucky in a strange way. They could have used all those passwords and bank details I kept emailing myself to access my accounts. The data loss was bad, but account takeover would have been catastrophic.
What I didn't realize then is that the real threat isn't what attackers can see. It's what they can become. An email account is basically a gateway to everything else you own online. Once they're in there, they can reset passwords, drain bank accounts, impersonate you across every service. The deletion was painful, but a complete account takeover would have destroyed me.
## Why this keeps cascading once it starts
Once one core account is compromised, others tend to follow quickly.
By the time most people realize something is wrong, multiple accounts are already involved. Cleaning it up becomes time consuming, stressful, and disruptive.
The damage is not always financial. Lost files, missed messages, and impersonation have real personal and professional consequences even when no money is stolen.
## The attack vectors people rarely think about
Many real compromises come from places that feel routine.
Calendar invites carry links and reminders that feel trusted. People accept them reflexively.
OAuth and sign-in flows feel safer than passwords, so people approve access quickly. That access often survives password changes because it was never tied to the password in the first place.
Browser extensions accumulate quietly. They update silently. Permissions stay broad. One compromised extension can observe sessions and modify pages without ever looking like malware.
Recovery paths are often forgotten entirely. Backup email addresses, trusted devices, linked accounts. Attackers do not need to break the front door if the side door is unlocked.
Shared devices create long-lived access in environments that no longer exist. Trust lingers long after context changes.
None of this feels malicious in the moment. That is why it works.
## Where AI makes this harder for normal people
AI did not invent new attacks. It removed friction.
Messages are now fluent, contextual, and emotionally tuned. What used to stand out blends into everyday communication. Small mistakes become easier to make, not because people are careless, but because the signal is harder to distinguish from normal life.
AI also enables adaptive interaction. Instead of a single scam message, attacks can unfold as conversations that respond naturally to hesitation or questions.
At the same time, AI tools are becoming part of daily workflows. People paste sensitive information into them without much thought. They authorize access to be helpful or efficient. Each approval feels minor. Collectively, they widen the attack surface in ways most users never map explicitly.
## Why platform choice alone no longer protects you
There is a comforting belief that choosing the right operating system solves most of this. Better defaults help, but they do not solve the core issue.
Identity flows across devices. Once access is compromised, it follows you everywhere.
This is why people feel blindsided after doing everything right. Updates were installed. Sketchy downloads were avoided. None of that mattered once trust was reused upstream.
## Work accounts versus personal accounts
Your work email operates under different rules.
Your employer controls your work account. They can see what you're doing, enforce password changes, require two-factor authentication, and reset your access if needed. Your IT department will notice if someone is using it from a strange location or accessing unusual data. But you have less control over recovery if something goes wrong.
Work account compromise is worse in different ways. An attacker gains access to your company's data, your coworkers, and potentially customer information. The problem spreads beyond you.
Personal accounts are yours to protect or neglect. No one is watching. You control recovery, but you're also alone in defending it.
Protect your work account like it matters to everyone else, because it does. Use the strongest authentication your employer allows. Don't reuse that password anywhere. Assume it's being monitored. If you suspect it's compromised, tell IT immediately.
Your personal accounts matter more to you than anyone else will ever know. That responsibility is entirely yours.
## So where does antivirus fit now
Antivirus still has a place. It helps catch known malicious software and obvious bad installers, especially on Windows.
It just is not what usually saves people anymore.
Most modern compromises do not involve infecting the machine at all. They involve inheriting access. Antivirus cannot stop you from logging into the wrong place or approving the wrong thing.
It is a seatbelt, not the steering wheel.
## Understanding data breaches
When you hear that a service you use suffered a data breach, it's worth understanding what that actually means.
A breach means attackers got data that shouldn't be public. If it's a password, that password is now known. If it's your email and password together, that combination is in a list somewhere that gets shared and tested against other services.
Check if you're in a known breach at [Have I Been Pwned](haveibeenpwned.com). Enter your email and you'll see which services leaked your information. This is useful. Not panic-inducing. Just useful.
A breach is past tense. Your password was leaked in 2018. That doesn't mean someone is using it now. But if you reused that password on other sites, those accounts are exposed.
This is why password reuse is so dangerous. One old breach at some forgotten service becomes a key to your email, banking, or work accounts years later.
The action is simple. If you were in a breach for a service that knows your password, change it. If you used the same password elsewhere, change those too. If the breached service offered two-factor authentication and you didn't use it, enable it now.
Most people are in multiple breaches. You probably are too. That's normal. The breach that matters is the one you don't know about yet. The one where you kept the same password everywhere.
## Spotting compromise before it spirals
There are early signals before the damage becomes obvious.
Check your account activity periodically. Most email and cloud services show where you're signed in and recent login locations. An unfamiliar city or device in that list is a genuine warning sign.
Recovery email or phone number changes are a red flag. If you suddenly can't use your backup email to reset a password, someone may have changed it. Same with linked phone numbers or authentication apps.
Connected apps and permissions creep slowly. Services like Google and Microsoft show what third-party apps have access to your account. If you see apps you don't recognize, or apps with permissions you don't remember granting, revoke the access. It's usually one click.
Two-factor authentication breaks the account takeover chain. If someone has your password but not your phone, they still can't get in. That friction is what stops most attacks.
## Behaviors that expose you more than others realize
Reusing passwords across sites means one breach ripples everywhere. A breach at some obscure service leaks credentials that work on Gmail or your bank. Password managers let you use different passwords everywhere without memorizing them.
Approving account access without reading what's being requested is risky. That app asking for "calendar and email access" might only need one of those. Read the request before clicking approve.
Public WiFi creates a different problem than it used to. The WiFi itself isn't the issue. The issue is attackers intercepting login traffic. VPNs help, but real protection comes from password managers autofilling credentials and services using encryption. Don't manually type passwords on public WiFi.
Clicking links in emails, even from people you know, is riskier now. Those emails can be impersonated or accounts can be compromised. If something seems unusual, go directly to the website instead of clicking the link. Especially with financial and account management emails.
## Anti-patterns: What NOT to do
Some habits feel convenient but directly enable compromise.
Do not share passwords with family members, even in emergencies. Once shared, you lose control. You can't change it without inconveniencing them. If they're compromised, so are you. If they leave or your relationship changes, you have a password you never reset. Use family plans or shared password vaults instead.
Do not write passwords down and leave them accessible. A notebook on your desk, a sticky note in your wallet, or a note in your phone is worse than a password manager. No encryption. No backup. No way to update everywhere at once.
Do not use the same password or PIN pattern across accounts. This is the core vulnerability that breaks everything. One breach becomes an attack on all your accounts.
Do not disable security notifications or two-factor authentication because they're inconvenient. They're inconvenient by design. That inconvenience is what stops attackers.
Do not ignore unusual activity emails from your accounts. Check them. If they're real, you need to know. If they're phishing, at least you're awake and can respond.
Do not grant app permissions you don't understand. That app asking for "calendar and email access" can now see every conversation you've had and every meeting you're attending. Read what's being requested. It should match what the app does.
Do not type passwords on public WiFi. The WiFi isn't the vulnerability. The vulnerability is someone intercepting your login. Use a password manager so it autofills, or wait until you're home.
Do not leave old accounts open and forgotten. An old email you don't use, an old social media account, a service you abandoned. These become recovery paths for attackers. Delete them or change their passwords if deletion isn't possible.
## For families and less technical users
Shared accounts with family are riskier than they seem. A shared Netflix account is fine. A shared email or cloud account is a serious risk because anyone with access can reset other accounts.
Children's accounts should be separate, even if they're young. An account a 10-year-old uses for school shouldn't be shared with the whole family.
Elderly or less tech-savvy family members are often targeted specifically. Attackers know they're less likely to recognize phishing or social engineering. If a parent or grandparent is asking you to help verify their account, double-check the request actually came from that service.
Support channels become attack vectors when attackers impersonate them. A call claiming to be from your bank asking you to verify information should be treated as suspicious. Legitimate support never asks for passwords.
## Mobile-specific reality
The line between apps and accounts is blurrier on mobile. An app installed from your app store has permissions to see your location, contacts, photos, calendar, and more. If the app is compromised, that's a live connection to your personal information.
Sign-in-with-Google or sign-in-with-Apple defaults are convenient but they also mean that Google or Apple now has another connection tracking what you're doing. More importantly, if someone compromises your account, they get access to every app you've signed into that way.
Android and iOS protect you in different ways, but both flow personal data through your account. The account is still the single point of failure.
## What actually helps
The defenses that matter now are different from what most people expect.
Two-factor authentication is the most effective thing you can do. It breaks the account takeover chain. Even if someone has your password, they still can't get in without your phone or authentication app. Use it on email, cloud storage, and banking. Those are the accounts that unlock everything else.
A password manager changes the math entirely. Chrome and Apple Keychain both work well. They generate random passwords automatically, so you never have to come up with one yourself. More importantly, they make it trivial to use different passwords everywhere. One breach stops being a key to all your accounts.
Periodically check what apps have connected to your accounts. Google and Microsoft both show you this. Revoke anything you don't recognize or don't remember approving. That access often survives password changes because it was never tied to your password in the first place.
Watch for unusual activity. Most services show you where you're signed in and recent login locations. An unfamiliar city or device is a genuine warning sign. Pay attention to password reset emails you didn't request. Those are often the first signal something is wrong.
Set up backup authentication methods and store them safely. Recovery email, phone number, recovery codes. You need these if you get locked out, but they're also attack vectors if someone else controls them. Keep them secure, but don't forget where you put them.
What doesn't help as much anymore? Antivirus software, avoiding downloads, keeping a clean system. Those still help, but they don't solve the modern problem. The attack surface moved, and so should your defenses.
## How to actually implement this
The biggest gap between understanding the problem and staying safe is actually doing something about it.
Don't reuse passwords. Use the password manager built into your browser or phone. You already have it.
If you use Chrome or Android, use the password manager that comes with it. If you use Apple devices, use Keychain. Both work everywhere. Both are encrypted. Both sync across your devices. You don't need anything else.
When you create a password on a website, let the password manager generate a random one. Don't come up with it yourself. Don't try to make it memorable. The whole point is that you never have to remember it or type it. The password manager fills it in.
The temptation is to reuse a password you already know because it feels simpler. It's not. It's the opposite. One breach leaks that password everywhere.
What doesn't work? If you email yourself a password, it's unencrypted and accessible to anyone with your email. A desktop text file has no encryption and anyone with access to your computer can see it. A notebook on your desk is a physical security issue. It can be photographed or stolen. A spreadsheet of passwords is centralized and unencrypted, so if it's stolen, the damage ripples everywhere. A phone photo of a password note gets backed up to the cloud and becomes searchable.
These approaches are worse than reusing the same password because they're unencrypted and centralized. One breach or one moment of access exposes everything.
Use the password manager. Let it generate random passwords. Use a different password for every site. Enable auto-fill so you never type passwords manually, especially on public WiFi. One breach stops being a key to all your accounts.
For critical documents, use a combination of physical and digital storage.
Keep the originals in a physical safe or safe deposit box. Birth certificates, passports, property deeds, insurance policies, medical records, financial statements. Not on your desk. Not easily accessible. These are documents you rarely need, so the inconvenience of accessing them is worth the security.
Scan them or take photos and store the digital copies in cloud storage. Google Drive, Microsoft OneDrive, or iCloud all work. Enable two-factor authentication on that account. You get access from anywhere and automatic backup, but the encryption and authentication keep it protected.
Don't keep important documents on your desktop or in random folders. Don't email them to yourself as attachments. Don't store them on a USB drive left in a drawer. Those feel convenient but they're not actually protected.
For recovery codes from two-factor authentication, print them out or write them down and store the physical copy in a safe place. A safe or safe deposit box. Not in a desk drawer. Not a photo on your phone. Not in unencrypted notes. You need these if you get locked out, but if someone else finds them, they become an attack vector.
The pattern is the same: don't rely on a single location. Don't sacrifice security for access. Use multiple layers, both physical and digital backup, so one failure doesn't lose everything.
## If you realize you're compromised
Act fast. The first 24 hours matter.
**Step by step:**
1. Use a clean, trusted device and go directly to the real website. Don't click links in emails or messages. Type the URL yourself or use a bookmark you know is safe.
2. Change your email password immediately. Use a strong, unique password. Email unlocks everything else.
3. Sign out of all sessions. Most email and cloud services have an option to sign out everywhere at once. This invalidates any active sessions attackers might be using.
4. Check for persistence. Look for email forwarding rules, filters, or delegates that you didn't set up. Attackers often leave these behind to maintain access even after you change your password.
5. Review connected apps and devices. Check what devices are signed in and revoke any you don't recognize. Check what third-party apps have access to your account and revoke anything suspicious.
6. Was your email compromised? If yes, change passwords on critical accounts immediately. Financial accounts, healthcare, government services, and your phone carrier. Assume any account with a similar password is at risk.
7. Freeze your credit and set fraud alerts if financial accounts were involved. This stops attackers from opening new accounts in your name.
8. Continue monitoring. Watch for unusual activity across all your accounts. Check account activity logs regularly for the next few weeks.
## The real shift to internalize
Modern compromise is rarely about broken software. It is about normal behavior becoming predictable.
Logging in. Approving access. Staying signed in. Reusing trust across contexts.
These are not technical actions. They are everyday habits. That is why they are so easy to exploit.
## What really matters
If modern compromise feels unfair, it is because the rules changed quietly.
Your computer did not suddenly become unsafe. The way trust moves through your digital life did.
Once you start thinking in terms of identity, sessions, and approvals, these incidents stop feeling mysterious. They start feeling structural.
Not because systems are weak, but because trust is easier to steal than code is to break.
---
# A Practical Way to Think About RAG
Canonical: https://nick.karnik.io/blog/how-rag-works
Published: 2025-12-12
Cite as: Nick Karnik, "A Practical Way to Think About RAG", nick.karnik.io (2025). https://nick.karnik.io/blog/how-rag-works
Retrieval-Augmented Generation (RAG) shows up constantly in conversations about LLM applications, especially once private or fast-changing data enters the picture. What I kept noticing was a gap between two kinds of explanations. Some stayed so abstract that it was hard to tell when RAG actually helped. Others jumped straight into tools and pipelines without first explaining what problem the system was really solving.
This is the mental model I keep coming back to when evaluating RAG systems. It is not exhaustive, but it is enough to make informed design decisions and to recognize when RAG is likely to help and when it is likely to cause problems.
## Why RAG exists
Language models are strong at reasoning over text, but they operate inside a fixed knowledge boundary. They do not know your internal documents, policies, or product details unless those are explicitly provided at inference time. They also do not update themselves as your information changes.
When a question depends on knowledge outside the model’s training data, the model has no mechanism to retrieve it on its own. Without help, it fills in gaps using general patterns, which is often where hallucinations start.
RAG exists to address this limitation. It gives the model access to relevant external information at the moment it generates an answer, without retraining or fine-tuning the model itself.
That distinction matters. RAG does not make the model smarter. It makes the system more grounded.
## A useful way to think about it
The simplest way to think about RAG is as a separation of responsibilities.
The model is responsible for reasoning, synthesis, and language. The system around it is responsible for deciding what information the model should see.
If you ask a question that depends on internal context, the quality of the answer depends almost entirely on whether the right reference material was placed in front of the model first. RAG is the mechanism that performs that selection.
Once you frame it this way, most debates about RAG become debates about retrieval quality rather than model behavior. It explains why systems can feel unreliable even when the model is doing its job.
## The basic flow, with emphasis on what matters
Most RAG systems follow the same general pattern, but not all parts are equally important.
Documents are first split into chunks. These should be large enough to preserve meaning but small enough to be retrieved selectively. Chunking is one of the most underestimated parts of RAG, and it is where many systems quietly go wrong.
In practice, chunk boundaries often need to respect document structure, such as sections or paragraphs, rather than arbitrary token counts. Some overlap between chunks is also common, not to improve recall in theory, but to avoid cutting important context in half.
Each chunk is then converted into an embedding that represents its semantic meaning. When a user asks a question, the question is embedded as well, and the system retrieves the chunks that appear closest in meaning.
Embedding quality matters, but it rarely compensates for poor chunking or unclear queries. Most retrieval failures show up well before vector similarity becomes the limiting factor.
Those retrieved chunks are added to the prompt along with the user’s question. The model then generates a response based on that supplied context.
The loop itself is simple. The difficulty comes from making each step reliable under real data.
## A concrete example that usually works
Imagine an internal policy document that covers refunds, eligibility criteria, timelines, and edge cases. A user asks, “Can customers get a refund after 30 days?”
With RAG, the retrieval step might surface three chunks: one defining eligibility, one describing standard timelines, and one listing exceptions. The model answers using those specific sections instead of relying on general knowledge about refunds.
If the answer is correct, it is because retrieval surfaced the right material. If it is wrong, the problem is almost always that an important chunk was missed or that irrelevant context crowded out the relevant one.
This pattern repeats across use cases.
## A second example, where RAG often fails
A common failure case shows up in troubleshooting or operational knowledge bases.
Suppose you have a long document describing how to debug a production issue, including prerequisites, conditional steps, and warnings. A user asks a targeted question like, “Why does service X fail only after a config reload?”
Retrieval may return chunks that mention service X and config reloads, but miss a critical section explaining an ordering constraint or a hidden dependency. The model produces an answer that sounds reasonable, cites the retrieved context, and is still wrong in a way that is hard to detect.
This kind of failure is subtle. The system appears to work. The answer is coherent. But an important constraint was never retrieved, so the model could not reason about it.
This is one of the reasons RAG systems can feel unreliable in operational settings. They fail quietly when retrieval misses the one piece that actually matters.
## What RAG does well, and what it does not
RAG works best when the task involves synthesizing information from a body of text that already contains the answer. It is well suited for policy questions, documentation lookup, and knowledge-based summarization.
It is much less effective when correctness depends on precise values, strict ordering, or full coverage of edge cases. In those situations, missing context is not a minor issue. It invalidates the answer.
This is also why prompt tuning rarely fixes weak RAG systems. If retrieval is off, prompting only rearranges the same incomplete inputs.
## When RAG is the wrong choice
RAG is often treated as a default architecture, but in many cases it introduces more complexity than it removes.
If your dataset is small and stable, fine-tuning or even simple in-prompt examples may be more reliable. If the task requires deterministic outputs, structured extraction, or exact correctness, a rules-based or programmatic approach is usually safer.
RAG shines when the problem is about informed synthesis, not enforcement or computation.
## A simple way to visualize the system
Here is the basic flow. Most complexity in real systems is layered on top of this, not a replacement for it.
 ### What each step does:
**User question**
Someone asks something like "Can customers get a refund after 30 days?" This triggers the RAG pipeline. The system needs to find relevant information to answer this specific question.
**Embed the question**
The question gets converted into a vector embedding that captures its semantic meaning. This is not about matching keywords. It is about what the question actually means. "Refund policy for late requests" and "Can I get my money back after a month?" would produce similar embeddings even though the words are different.
**Retrieve relevant chunks**
The system compares the question's embedding against all the chunks in your document store and finds the ones that are semantically closest. These are the chunks most likely to contain relevant information. This usually returns somewhere between 3 and 10 chunks.
**Add chunks to the prompt**
The retrieved chunks get inserted into the prompt along with the original question. Instead of just asking "Can customers get a refund after 30 days?", the system is now asking "Given these policy sections: [chunk 1, chunk 2, chunk 3], can customers get a refund after 30 days?"
**Generate a response**
The model reads the question and the context chunks, then generates an answer. It does the same reasoning it always does, but now it has the specific information it needs. The quality of this answer depends almost entirely on whether retrieval found the right chunks.
## Closing
Keeping this flow in mind helps keep systems understandable, even as more advanced techniques are layered on top.
RAG is best understood as a pattern, not a product or a feature. It is a way to control what information a language model sees at the moment it produces an answer.
Many modern systems layer additional techniques on top of this pattern, such as hybrid retrieval, reranking, or multi-step queries. These can improve results, but they do not change the underlying shape of the system. Retrieval still determines what the model can reason about. Generation determines how that reasoning is expressed.
As a starting point, this mental model is enough to decide whether RAG belongs in a system and where the real risks are. Once that’s clear, deeper implementation choices become easier to make and easier to question.
---
# Build for Speed: What It Takes to Release Fast
Canonical: https://nick.karnik.io/blog/build-for-speed
Published: 2025-10-23
Cite as: Nick Karnik, "Build for Speed: What It Takes to Release Fast", nick.karnik.io (2025). https://nick.karnik.io/blog/build-for-speed
Everyone wants to move fast, but not everyone knows how. It sounds simple: automate more, release often, catch problems earlier. But in practice, it’s complicated. Speed is fragile. It depends on hundreds of small things working together such as your CI, your tests, your telemetry, your rollback path, and how much trust your team has in all of it.
Over the years I’ve worked on large systems at Microsoft, Google, Salesforce, Tableau, and T-Mobile, and on smaller teams where everything was built from scratch. Earlier, at the Institute for Disease Modeling, we ran large-scale epidemiological simulations on HPC clusters, basically supercomputers, before moving workloads to the cloud. Whether it was data pipelines, developer platforms, or consumer products, the challenge was always the same: how do you move fast without breaking everything?
Releasing fast isn’t about typing faster or skipping QA. It’s about shortening the distance between writing a line of code and knowing it’s safe in production. It’s about how quickly you can detect a problem, roll back, and try again. The best teams aren’t fearless. They’re steady because they’ve built systems that make it safe to move.
At Microsoft, when we shipped new features for Bing, we started with 0.3 percent of traffic. That sounds tiny, but at that scale it was plenty with millions of queries a day, enough to see real signal without risking the system. At Google, on Gemini’s developer tools, we sometimes began closer to ten percent. The numbers weren’t sacred; they were dictated by confidence. Some launches went from 0.3 to 100 percent in a single day. Others crept from 0.3 to 25 to 100 over a few weeks. The pace wasn’t set by process; it was set by how long it took for telemetry to appear on dashboards and for us to trust what we saw. At that size, data can take a day or two to roll in. You move at the speed of truth.
Startups don’t have that problem. They see what happens right away - a spike in errors, a message from a user, or a Slack alert. That closeness is their advantage. When feedback is instant, you don’t need ceremony. You just fix it.
Speed isn’t something a CI system gives you. It’s something you build around it. You can use GitHub Actions, Buildkite, Jenkins, whatever you want. The tool doesn’t matter as much as having a workflow that actually works for your team. What matters is that you can trust the system, that it runs the right checks, and that you can reproduce most of it locally before you even push a commit. Docker helps with that. If your local setup behaves like your CI environment, you save yourself an entire cycle of guesswork.
Back when I worked on MSN, our build used to take twenty-four hours. A single bad check-in could cost everyone a full day. That’s why "don’t break the build" was almost a religion. Some teams would even make you wear a funny hat or post your name on a board if you did. It sounds childish, but the idea made sense: when one person slows the whole team, everyone feels it. The wall of shame wasn’t the point. The point was that catching issues early helps everyone move faster.
A good release isn’t one that looks fancy on a dashboard. It’s one that happens quietly, automatically, without anyone hovering over it. You write code, you test it locally, you push it, and the system takes it from there. It runs lint, type checks, and deeper tests you can’t afford to run locally, and if everything’s green, it ships. You shouldn’t need a meeting for that.
Most of the pain in releasing fast comes from bad tests and slow pipelines. I’ve seen test suites hang for hours, flaky tests that waste days, and dependencies between teams where your build breaks because someone else’s tests fail. Whether it’s culture, tooling, or just a black-box pipeline, the result is the same: time lost and trust eroded. Logging and telemetry matter as much for your build system as they do for production. You need to see how long each stage takes, where the bottlenecks are, and which tests are dragging you down. There’s usually an easy win hiding there. Not everything can be shortened, but you can parallelize, split workloads across containers, or move slow integration tests to a nightly run. Any test that takes more than a few seconds is worth questioning.
Tests that run in watch mode or trigger on file changes are a huge help. When type checks or lint errors show up while you’re still coding, you fix them immediately instead of waiting for CI to fail later. That’s the idea behind "shift left." If you picture the entire software process as a line, code on the left, production on the right, then shift left just means catching problems earlier in that line. The further right an issue gets, the more expensive it becomes to fix. Finding something during coding or pre-commit takes seconds. Finding it after deployment can take hours, with more people involved. The goal is to push every form of feedback as far left as possible, where it’s still cheap and fast to act on it.
Speed isn’t just how fast you can push code; it’s how quickly you can know if something went wrong. Every release should tell you what happened, not make you guess. After a deploy, you check staging first. There should be zero errors, all tests passing, and no unexplained warnings. If there’s a warning, it should already be tied to a bug so whoever looks at it knows it’s known and being worked on. That kind of traceability matters when hundreds of people are touching the same system.
You also watch the basics: latency, crash rates, availability are the things that actually matter to users. For search results, we targeted under 300 milliseconds end-to-end. Each downstream dependency had its own smaller budget: 100 ms here, 200 ms there. In a distributed system it’s like a train passing through stations. Each service has a small window to respond. If it misses that window, you move on, unless it’s critical. At Bing, for example, search results had to arrive, but ads or side answers could be skipped if they were late. It kept the system responsive without blocking on slower dependencies.
You need alerts wired into all of this: Slack, email, text, pager, whatever your setup is. The best systems tell you before the user does.
Good dashboards are underrated. Bad ones slow you down because you can’t tell what broke. Great ones let you glance, see the problem, and move on. The goal is to automate as much of that feedback as possible so humans aren’t the bottleneck. When your deploys can move from check-in to staging to production automatically, with telemetry watching the path the whole way, that’s when shipping becomes easy.
Having a solid rollback mechanism is just as important as releasing. You can’t move fast if recovery is slow. Blue-green deployments, feature flags, and one-click rollbacks make mistakes survivable. The faster you can undo something, the braver you can be about shipping again. Every system should have a clear escape hatch. Rollback shouldn’t require a war room.
Releasing fast isn’t just a technical problem; it’s a hygiene problem. Every flag, every flaky test, every commented-out block of code adds friction. At Google we deleted old feature flags about two weeks after a release. Flaky tests were tracked, tagged, and fixed after three failures. Each one got a bug filed automatically, and on-call engineers were expected to watch them. At smaller startups I’ve kept the same principle even if the tooling was lighter: fix or delete, but don’t ignore. Every ignored failure is debt with interest.
There’s a misconception that moving fast means writing sloppy code. It’s the opposite. The only way to move fast for long is to have good habits. You can hack your way to a few quick releases, but you can’t sustain it without discipline. Clean code, reliable tests, clear ownership is what speed is built on.
When a team really learns to release fast, it doesn’t feel like speed anymore. It feels calm. No adrenaline, no late-night deploy drama, no heroics. You merge, the pipeline runs, the telemetry lights up, and you go back to work. The system takes care of you because you’ve taken care of it. That’s the quiet truth about shipping fast. It’s not about risk or bravado. It’s about trust, in your process, in your code, and in each other.
---
# It's Not the Launch, It's the Landing
Canonical: https://nick.karnik.io/blog/its-not-the-launch-its-the-landing
Published: 2025-10-02
Cite as: Nick Karnik, "It's Not the Launch, It's the Landing", nick.karnik.io (2025). https://nick.karnik.io/blog/its-not-the-launch-its-the-landing
In technology we celebrate launches as if they were victories. The moment something goes live there is a demo, a blog post, a slide in a performance review. It feels like success. But a launch is not the finish line. It is only takeoff. The real test is whether the product lands.
Nobody remembers Apollo 11 as a triumph simply because the rocket cleared the pad. It was a triumph because the astronauts landed on the moon, achieved their mission, and returned home safely.
I saw this firsthand years ago at a security company. I built a feature that seemed minor at the time, a real-time status light that showed whether devices were online, idle, restarting, or updating. It worked across card readers, cameras, motion sensors, and alarms. There was no launch event, no fanfare. I wrote it in a couple of long nights because I believed it would help. And it did.
Support tickets dropped because technicians could see problems at a glance instead of digging through logs. Installations went faster because issues were obvious as soon as devices came online. If something went offline during setup you knew right away. Sales used it in demos. Customers could see right away it worked and they felt we were listening. Over time we expanded it so you could right click to control devices, group them, and take actions directly from the same interface. What began as a side project quietly transformed the product. That was a landing.
Plenty of products we all use tell the same story. [Gmail](https://workspace.google.com/blog/productivity-collaboration/celebrating-50-years-of-email) began as a quiet invite-only service. The landing was steady adoption until it became the default for billions. GitHub was not splashy either, but pull requests became the way modern software is written. Dropbox began with a short [demo video](https://www.youtube.com/watch?v=7QmCUDHpNzE) on Hacker News, and the landing came when sync worked flawlessly and spread by word of mouth. None of these succeeded because of the noise at launch. They succeeded because they landed.
We have also seen the opposite. Google Glass had a dazzling demo. It failed not because it couldn't launch but because people didn't want to wear computers on their faces. Microsoft launched the Zune to compete with the iPod but it never landed because it lacked an ecosystem and cultural pull.
So how do you tell whether something has truly landed.
**The landing test comes down to a handful of simple questions:**
> Did adoption continue after the initial spike or flatten out?
> Did retention improve after week two and week four or did users drop off?
> Did the product hold up under real load or collapse when it mattered?
> Did it replace an older workflow or did people drift back?
> Did customers bring it up unprompted as valuable or did it fade away?
> Did it achieve the goal it was built for?
If most of these questions can be answered with a clear yes, then you have a landing. If not, all you had was a launch.
A launch with no landing isn't neutral. It's a liability. It adds complexity and noise for no gain.
Launches are important. They mark the moment when something becomes available. But they are not success. They are liftoff. Success is when the thing survives contact with reality, scales under pressure, and earns its place in people's lives.
Anyone who has flown knows this truth. Takeoff is thrilling, but nobody claps when the plane leaves the ground. The relief and the gratitude come when the wheels touch down safely. In technology it is the same. Launches are exciting, but the real measure is whether the thing you built actually lands.
Launches are noise. Landings are history.
---
# How Engineers Can Use AI Effectively
Canonical: https://nick.karnik.io/blog/how-engineers-can-use-ai-effectively
Published: 2025-09-27
Cite as: Nick Karnik, "How Engineers Can Use AI Effectively", nick.karnik.io (2025). https://nick.karnik.io/blog/how-engineers-can-use-ai-effectively
AI is everywhere in tech conversations. Some people hype it as magic while others dismiss it as overblown. The truth is simpler. AI is a tool. Like any tool in engineering, its value depends on how it is used.
Used carelessly, it produces garbage. Used well, it creates leverage.
I don't rely on AI to write my code for me. I use it to learn faster, refine ideas, and clear out repetitive work so I can focus on the decisions and systems that matter. When I am exploring a new library, I can ask for examples in context. When I hit a confusing error message, I paste it in and get possible root causes in seconds. When I am choosing between two approaches, I can compare tradeoffs without having to dig through endless blog posts or Stack Overflow threads.
Most engineers stop at asking AI for snippets of code. That misses half the benefit. I use it as a critique partner. If I draft an API design, I will ask what edge cases I might be missing. If I sketch out an architecture, I will ask where it might break under load. If I put together a plan, I will ask it to challenge my assumptions. The answers are not always right, but even when they are off they push me to sharpen my own thinking and see blind spots earlier.
Instead of fighting AI, we should be embracing it as a tool. Human progress has always followed this pattern. Every major leap came from adopting new inventions and finding ways to make them useful. Electricity transformed how we lived and worked. Automobiles and airplanes collapsed distances. Computers and the internet reshaped entire industries. In just the last 150 years we have advanced more than in the thousands of years before, precisely because we learned to harness these tools. AI is simply the next in that line. It is a turning point, and like every tool before it, it will get better the more we push it to meet our needs.
A good example came up when I was reviewing a design that involved processing jobs from a queue where reliability mattered. The system needed retries, but it also had to avoid hammering a downstream API. I already knew about exponential backoff, but I wanted to see if there were edge cases I was missing.
I asked AI to critique the design. It flagged that without jitter, simultaneous retries from many clients could create a thundering herd problem. It also suggested layering in a dead-letter queue for jobs that failed after multiple attempts. Neither idea was new to me, but having them surfaced in seconds let me validate my assumptions quickly and confirm the design before I moved ahead.
**Initial design:**
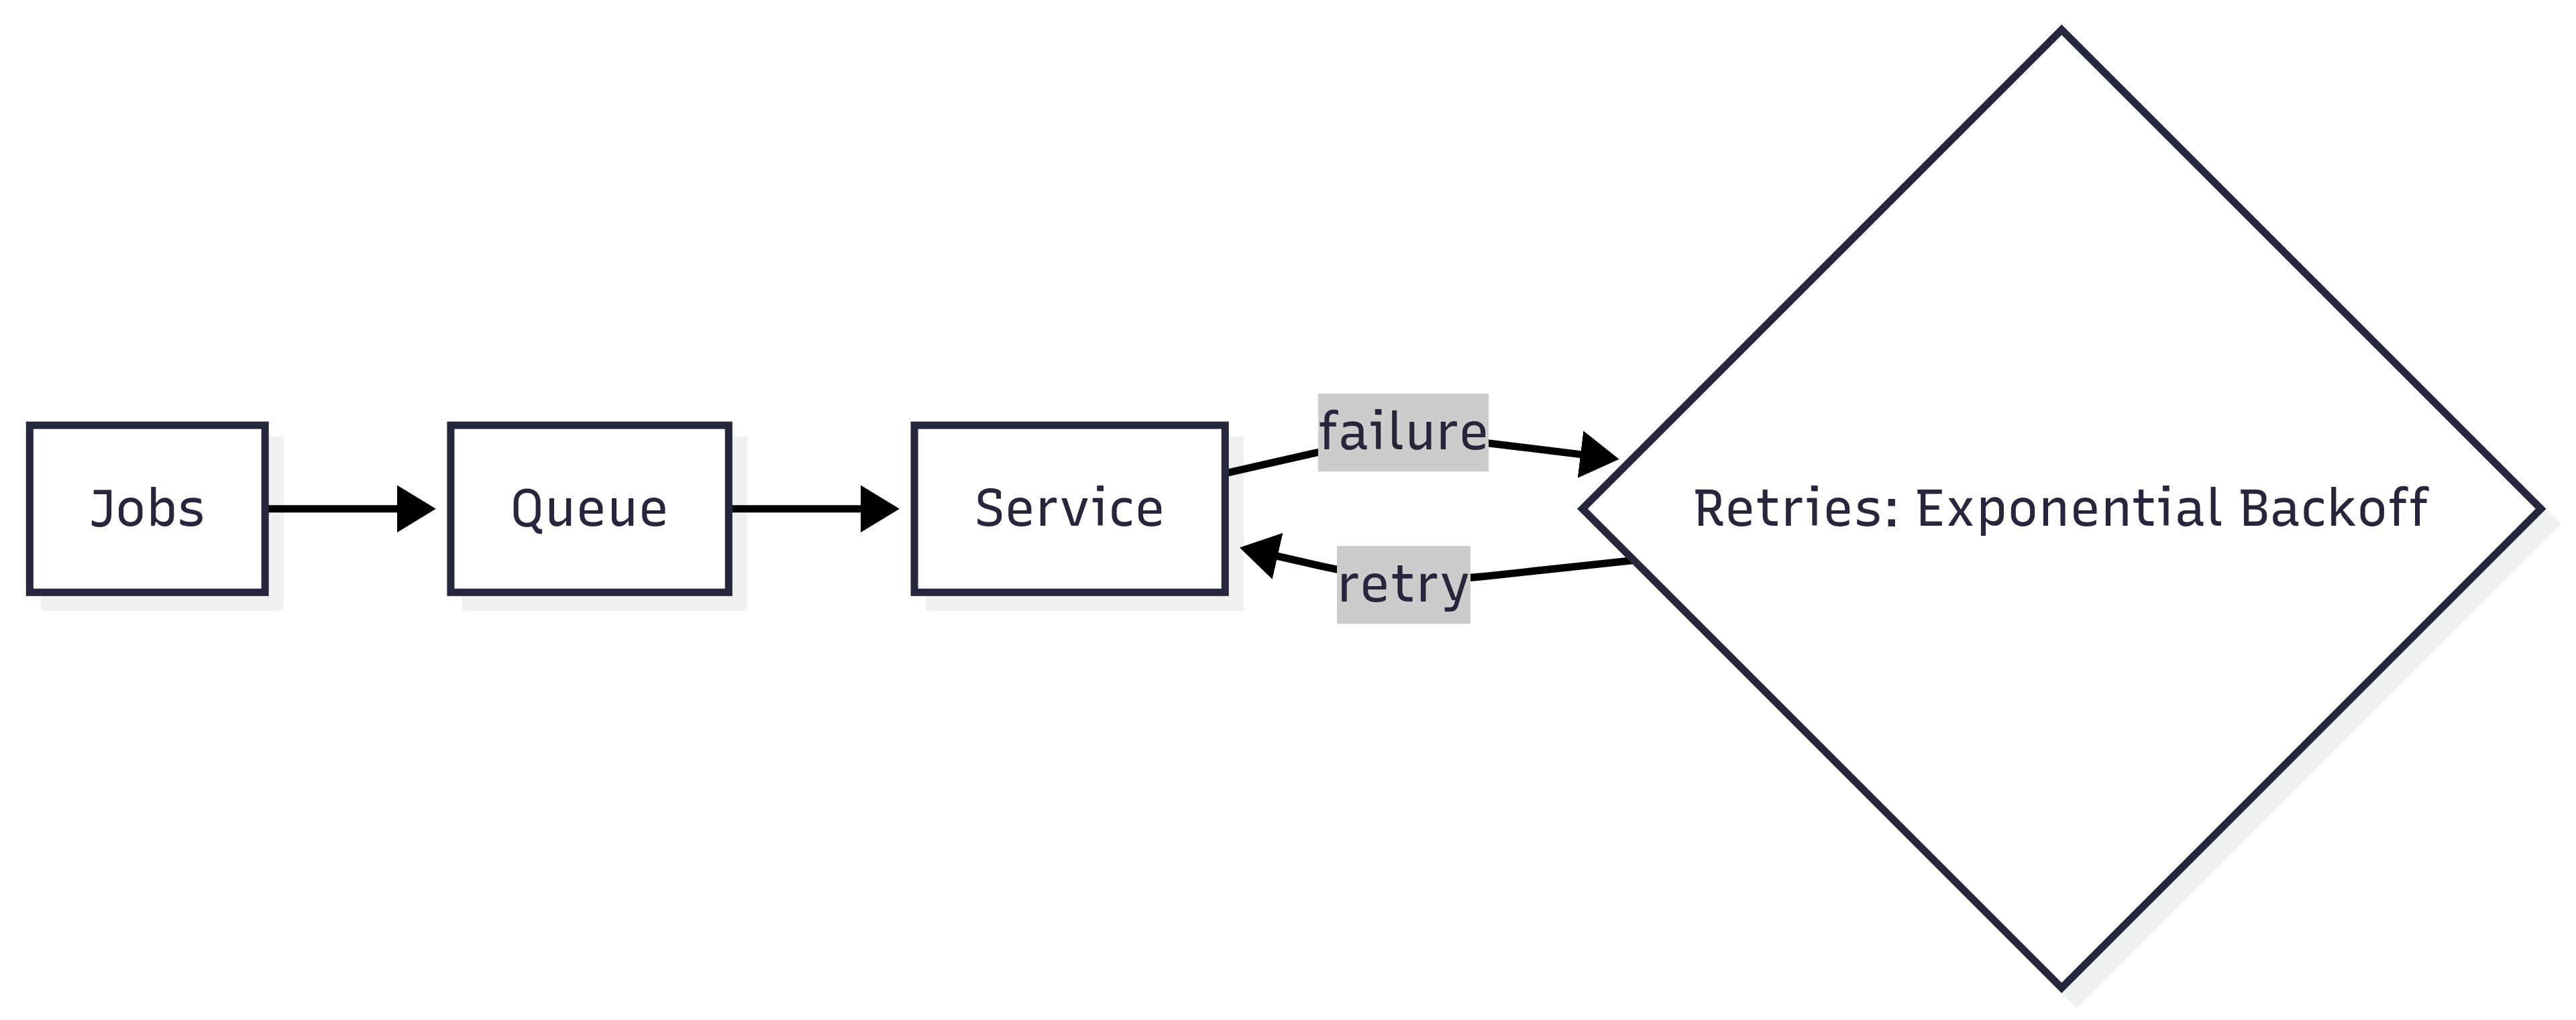
_Jobs move into a queue and are retried with exponential backoff on failure._
**AI-suggested improvements:**
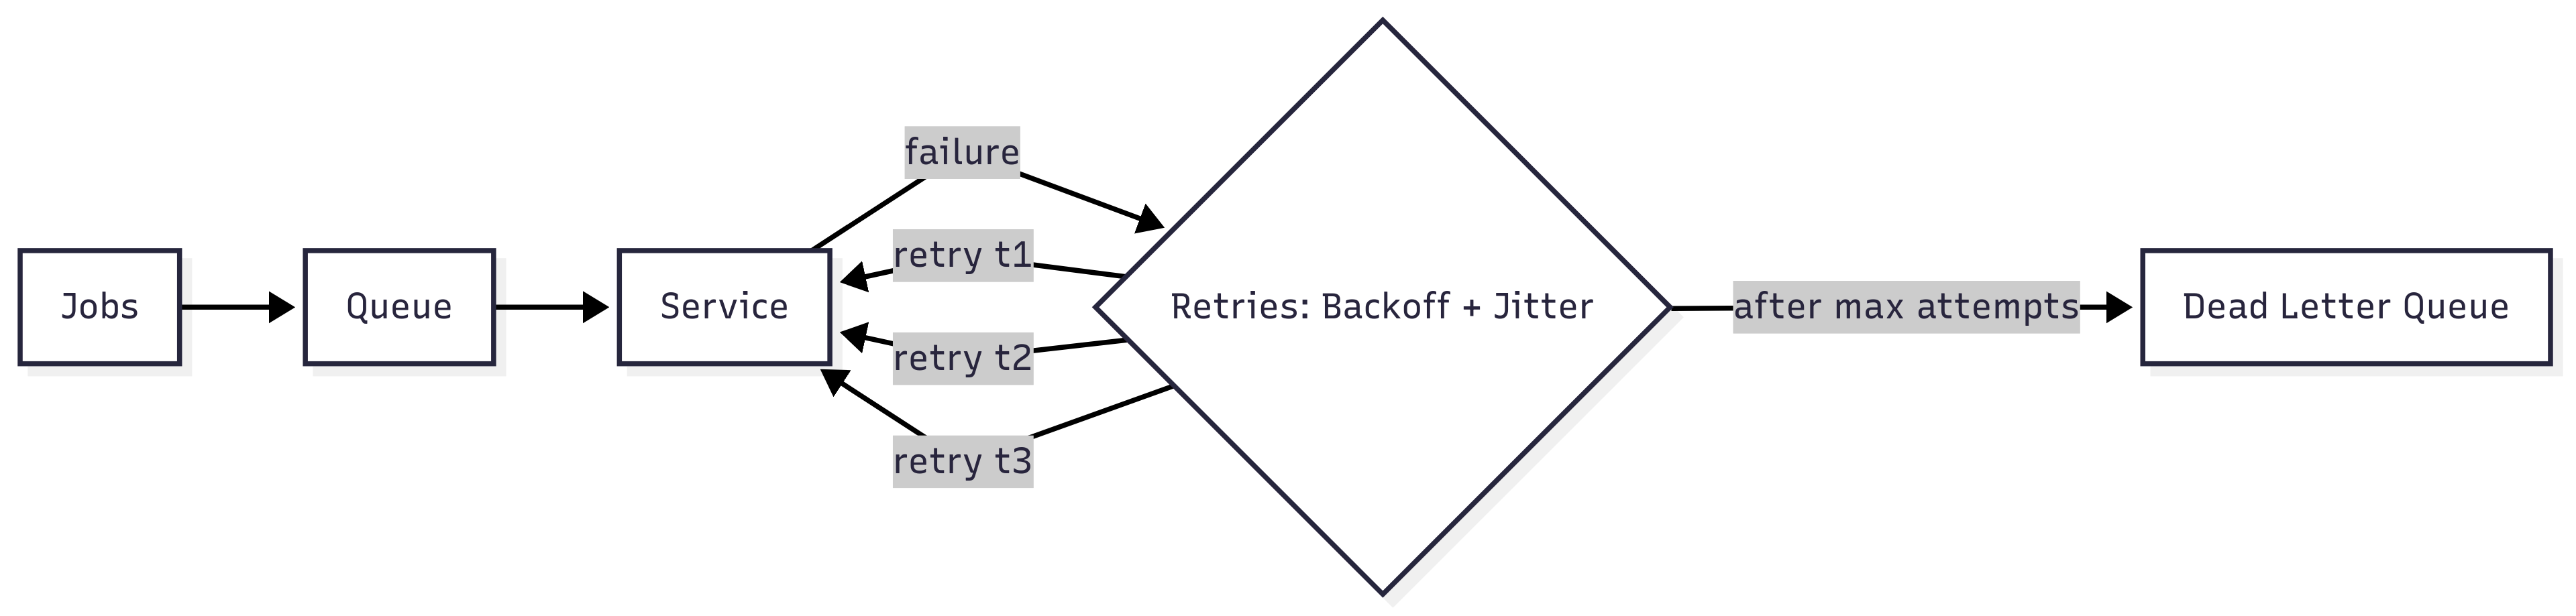
_Adding jitter reduces retry storms. A dead-letter queue catches jobs that fail after maximum attempts._
These weren't concepts I didn't know, but AI gave me a quick critique partner Instead of spending half an hour sanity-checking edge cases, I got feedback in seconds and could move ahead with confidence.
AI is also useful for clearing grunt work. Boilerplate code, simple tests, migration scripts, or even the first draft of a design document are all tasks it can handle quickly. What it cannot do is make judgment calls. If I don't understand what the model produced, I don't use it. That discipline makes the difference between outsourcing and acceleration.
There are also easy ways to get this wrong. If you paste AI-generated code into production without review, you will create problems later. If you use it as an excuse to stop learning, your skills will decay. If you rely on it to make critical design choices, you will end up with bloated and brittle systems nobody wants to own.
AI will not replace engineers in the near future, but an engineer using AI will.